



The 6 Differences Between Voice of Customer Software and Customer Intelligence

September 15, 2026

Every release ships with a bump in bug reports. Most of it is noise: users finding the new button, filing duplicates of known issues, hitting the same edge case that existed last month. The spike that matters looks almost identical in a ticket-count chart, which is why teams either escalate every bump and burn engineering trust, or wait for volume to settle and lose two days.
The five signals that separate a real regression from a normal post-release bump are novelty of the theme, convergence across channels, version concentration, a shift in what users say they tried, and account concentration. None of them is a count. Each one asks what the reports say rather than how many arrived.
Volume is an aggregate of everything happening at once, which makes it the worst available instrument for the question being asked. A regression from a release and a marketing campaign driving new signups produce the same upward line. So does a holiday, an outage at an integration partner, and a competitor's migration offer sending confused users to your docs.
Teams compensate by setting thresholds, then discover the threshold is either so low it fires weekly or so high it fires after the incident channel already opened. The problem is not calibration. A count discards the only information that distinguishes the cases, which is the content of the reports.
This is the same structural gap covered in the 5 signals that a support ticket spike is actually an incident, framed there for support leads deciding whether to declare an incident. The question below is narrower and belongs to product and engineering: did the thing we shipped break something.
The single strongest signal. A regression produces a category of complaint that did not exist in the previous period, often at low volume. An ordinary bump produces more of the complaints you already had.
This is difficult to see with keyword alerts, because nobody wrote a query for a failure mode that did not exist yet. An adaptive taxonomy learns categories from the reports themselves, so a genuinely new theme surfaces as its own category on the day it appears rather than being absorbed into an existing bucket labelled something like "login issues."
The practical test: pull the themes present this week and absent last week, ordered by recency rather than volume. A real regression is usually near the top of that list before it is anywhere near the top of a volume chart.
A real break shows up in more than one place, because different users reach for different channels. The same failure appears as a support ticket, a review, a community post, and a message in a shared Slack channel, within hours.
A noise bump usually stays in one channel, because it is an artifact of that channel: a support macro change, a review prompt firing after an update, a community thread with a single loud participant. Convergence across independent sources is hard to fake and is the fastest available confirmation that something real is happening.
Regressions have a blast radius. If the reports cluster on a specific app version, browser, OS, region, or rollout cohort, that is close to diagnostic, because noise does not respect deployment boundaries.
This requires that reports carry that metadata and that it survives into analysis. Teams whose feedback arrives as unstructured text with the version stripped out lose this signal entirely, which is usually a pipeline problem rather than an analysis problem. The 6 fields every bug and feature request ticket needs covers what to capture so this check is available when it is needed.
Ordinary post-release reports are full of orientation language: where did, how do I, I cannot find. Regression reports are full of interruption language: it stopped, it used to, nothing happens, it worked yesterday.
That distinction is visible in the text long before it is visible in any metric. Reports referencing prior working behavior are the highest-signal subset of any spike, because a user only says "it used to work" when something changed. Filter for that phrasing pattern first.
Two spikes of identical size can carry entirely different exposure. Thirty reports spread across trial users is a different decision from twelve reports concentrated in enterprise accounts with renewals inside the quarter.
A flat feed cannot make that distinction. A customer context graph ties each report to the revenue, segment, and named account behind it, so the escalation decision is made on exposure rather than on count. This is also what makes the escalation persuasive to engineering, since the ticket arrives with the affected accounts attached rather than an assertion that it feels urgent.
In order, because the cheap checks eliminate most false alarms:
First, list themes present now and absent in the prior period. If nothing is new, it is almost certainly a volume bump rather than a regression.
Second, check whether any new theme appears in two or more independent channels. One channel means keep watching. Two means investigate now.
Third, check version and cohort concentration on the new theme. Clustering confirms it.
Fourth, read ten reports. Look specifically for prior-working language.
Fifth, check which accounts are affected before deciding severity. This is the step that determines whether it interrupts the sprint.
The decision rule: escalate on novelty plus convergence, size the response on account exposure. A team that escalates on volume will be consistently late, and a team that escalates on every new theme will be consistently ignored. When it is confirmed, attach the customer evidence to the ticket so engineering inherits the context rather than re-deriving it.
Usually within hours for anything blocking, and within a few days for issues that only appear in a specific workflow. The lag is driven by how often users hit the broken path, not by severity, so a serious break in a monthly workflow can stay quiet for weeks.
An incident is a service-level problem that triggers a response process, usually detected by monitoring. A regression is a behavior change that monitoring will not catch because nothing is technically down. Regressions are found in what users say, which is why they surface in feedback before they surface in dashboards.
Yes, and this is the main argument against threshold alerts. A theme that is new is meaningful at three reports if those reports converge across channels and reference prior working behavior. Waiting for statistical significance on a count is what produces late detection.
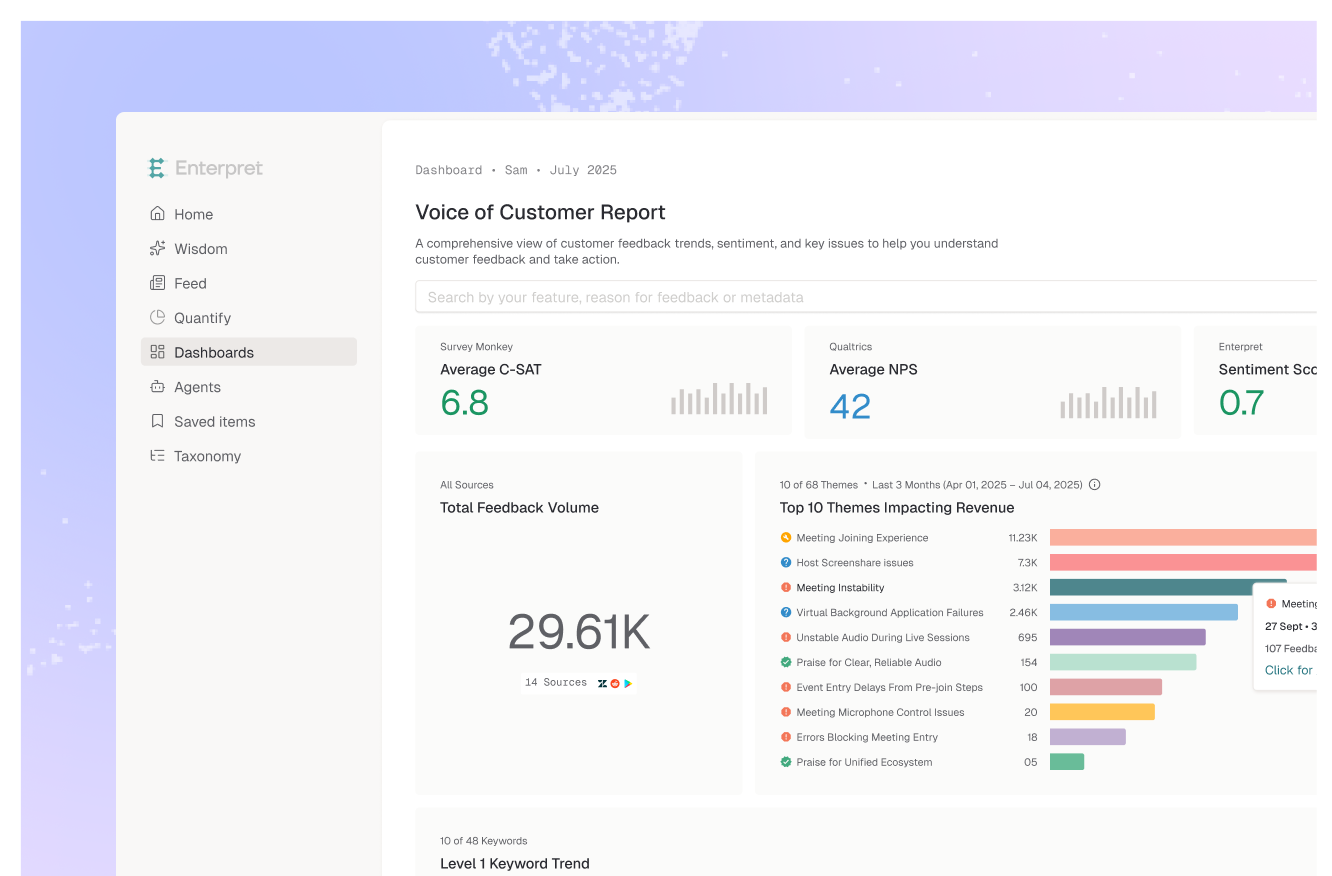
Enterpret ingests reports from 50+ channels and categorizes them in real time with an adaptive taxonomy that learns the product's own categories, so a failure mode nobody anticipated appears as a distinct new theme rather than falling into an existing bucket. The customer context graph then attaches version, segment, revenue, and account detail to that theme, which turns an early signal into a sized decision.
If regressions keep getting confirmed a day late, see how Enterpret surfaces new themes across every feedback channel.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.