



The 6 Differences Between Voice of Customer Software and Customer Intelligence

September 15, 2026

Standard bug ticket templates converged years ago on four fields: steps to reproduce, expected behavior, actual behavior, and environment. They are good fields. They also describe the defect entirely from the engineering side, which is why a well-formed ticket can sit in a backlog for three quarters without anyone being able to argue for it.
Six fields make a bug or feature request ticket actionable: the reproduction or the job, the customer evidence, the demand count, the revenue attached, the source link, and the loop-closing list. The first is the engineering half. The other five are the half that determines whether the ticket gets prioritized, and most templates have none of them.
The two problems get solved by different fields and only one of them gets a template. Engineering-side quality determines whether a ticket can be fixed. Customer-side evidence determines whether it will be.
The failure is visible in any mature backlog: hundreds of correctly formatted tickets, sorted by a priority field someone assigned from intuition at filing time and nobody has revisited since. The information that would reorder that list, who asked, how many, worth how much, exists in the support queue and never made it into the ticket.
For a bug: steps, expected, actual, environment, frequency. For a feature request: the job the customer is trying to do and what currently blocks it, written as their goal rather than their proposed solution. This distinction does real work. A request field that captures "add a bulk export button" loses the information that the customer needs scheduled delivery to a finance system, which a different and cheaper feature would solve.
Two or three verbatim quotes, with source and account attached. Not a summary of what customers want. The actual sentences. Quotes are what make a ticket persuasive in a room, because a paraphrase can be argued with and a customer's own words cannot. They are also what prevents the slow drift where a request gets restated through three people until it describes something nobody asked for.
How many distinct accounts have raised this, over what period, and whether the rate is rising or flat. A count with a trend beats a count alone: twelve accounts over two years and twelve in the last month are different tickets. This field is also the honest one, because most tickets that feel urgent turn out to have two requesters and a strong advocate. See detecting feature requests in support conversations.
Total ARR of the accounts that requested it, with anything inside a renewal window flagged. This is the field that changes prioritization outcomes more than any other, and the one almost no ticket template contains. It also reframes the conversation: engineering time is being allocated against revenue exposure rather than against the persuasiveness of whoever filed the ticket. See prioritizing feature requests from reviews and tickets.
A deep link to the originating tickets, calls, or reviews. Every claim in fields two through four has to be verifiable in one click, or the numbers get treated as advocacy. This is also what makes the ticket survive the engineer who picks it up six weeks later and needs context the filer never wrote down.
The accounts and contacts to notify when this ships. Attached at filing time, not reconstructed at release. This single field is the difference between a shipped fix and a shipped fix your customers know about, and reconstructing it after the fact almost never happens because by then nobody remembers who asked. See telling requesters their feature shipped.
Here is the practical problem with everything above. Fields two through six are the valuable ones and they are also the ones a support agent filing a ticket at 4pm will leave blank, because filling them means searching the help desk for other instances of the same issue, checking the CRM for each account's value, and pasting links.
That is five to fifteen minutes per ticket, at the moment in the day when the person has the least of it. So the fields exist in the template and stay empty, and the backlog reverts to being sorted by a priority dropdown.
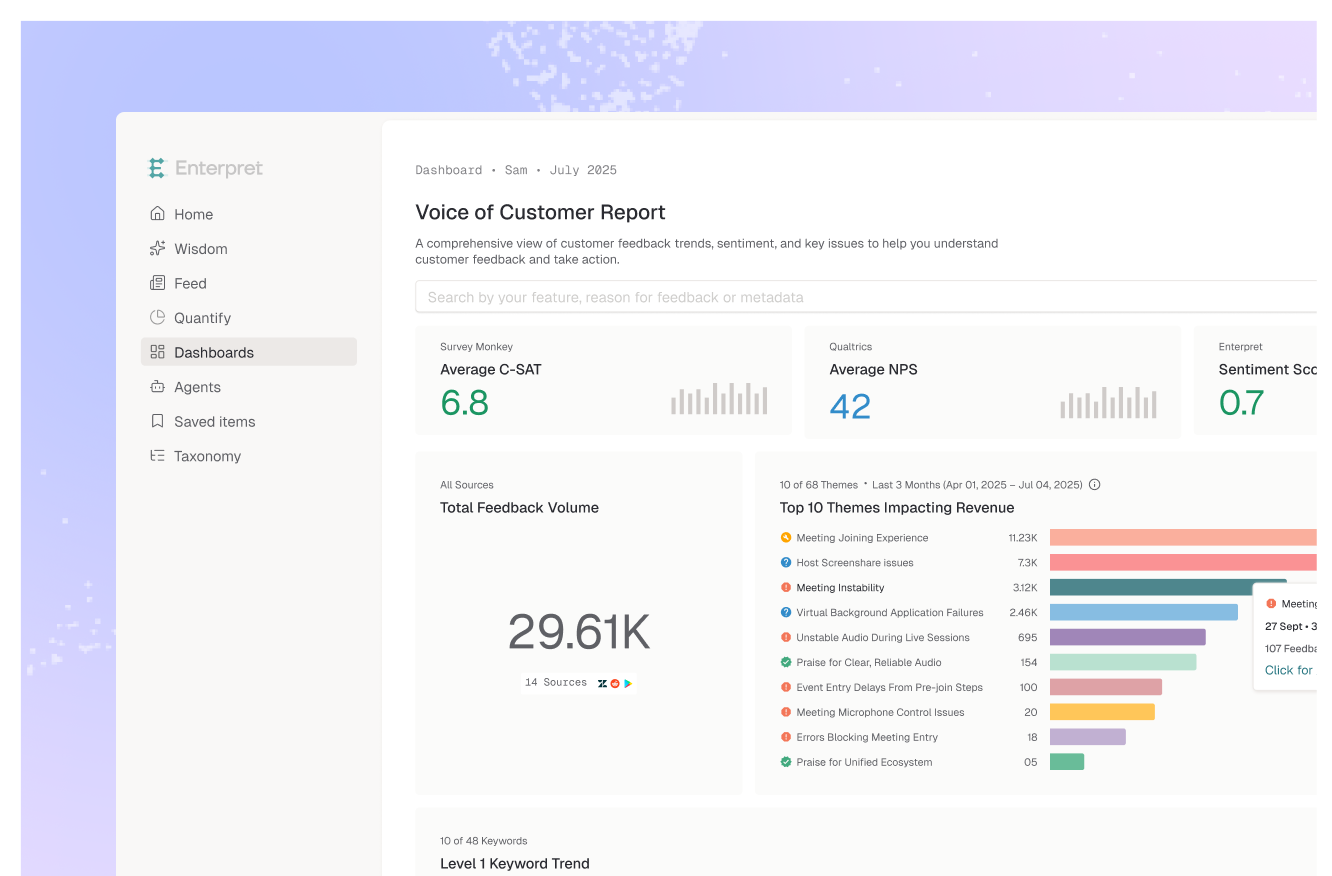
The only version of this that works is one where the customer-side fields are populated by the system rather than by the filer. The feedback is already categorized, the accounts are already joined to revenue, and the requester list is already a query. At that point the agent writes the repro and the quotes, and the count, the revenue, and the notify list arrive attached. See VoC platforms with Jira and Slack integrations and workflow integrations.
The honest caveat: automatic demand counts are only as good as the categorization underneath them. A count assembled by keyword matching will undercount badly, because customers describe the same problem in language that shares no keywords, and an undercount attached to a ticket is worse than no number at all.
Put fields one and two in the manual template and make them required. Keep them short: three quotes maximum, and a repro that fits on a screen.
Populate three through six automatically at filing and refresh them on a schedule, because demand and revenue change while a ticket sits. A ticket filed with four requesters that has nine by the time it reaches planning should show nine.
Re-sort the backlog against the refreshed numbers before each planning cycle rather than trusting priorities set at filing time. That re-sort is the entire payoff of the extra fields, and skipping it makes them decoration. See validating a feature request before you build it.
The decision rule: if a ticket cannot state how many accounts asked and what they are worth, it is not ready for a prioritization conversation, regardless of how well the repro is written.
The reproduction steps for a bug or the underlying job for a request, verbatim customer quotes, a count of distinct accounts that raised it with its trend, the revenue those accounts represent, deep links to the source records, and the list of contacts to notify when it ships.
A bug ticket documents behavior that differs from what the product promises, so it needs reproduction steps, expected versus actual behavior, and environment. A feature request documents a job the product does not support, so it needs the customer's goal rather than their proposed solution. Both need the same customer evidence fields.
Rank by the revenue of the accounts that requested it and the trend in the request rate, rather than by raw mention count or by a priority field set at filing. Re-sort before each planning cycle, since demand accumulates while tickets sit and the ordering set months ago is usually stale.
Enterpret categorizes feedback across tickets, calls, reviews, and surveys with an adaptive taxonomy that recognizes the same request even when customers describe it in entirely different words, which is what makes an accurate demand count possible. The customer context graph attaches the accounts and revenue behind each request and produces the list of who to notify at release. Tickets can be drafted into Linear or Jira with those fields already populated.
Record it, but not as the request. Customers propose solutions in terms of what they know exists, and a ticket written around the proposal frequently commits engineering to a more expensive build than the underlying job requires. Capture the job first and keep the proposal as context.
If your backlog is sorted by intuition rather than by demand, see how Enterpret handles product feedback analysis.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.