



The 5 Differences Between Claude Skills and MCP Servers (2026)

September 16, 2026

In HubSpot's State of AI research, 28 percent of customer service professionals reported using AI to collect and analyze customer feedback, making it the second most common service use case behind routing requests. Adoption stopped being the question a while ago. The teams running these systems in production have moved on to a harder one: the agent produces a confident summary, and nobody can tell whether it is right.
The answer is yes, with a condition. AI agents can genuinely retrieve across every channel, cluster at volume, detect emerging issues early, draft the narrative, and answer follow up questions in natural language. What they need first is a structured feedback layer: a taxonomy that holds still, context attached to every theme, full coverage, and traceability back to source records. Give an agent those four things and it performs. Point it at raw text and it improvises, which is a different product than it appears to be.
The usual framing pits AI against human judgment. That framing hides the actual variable, which is the structure of the data the agent reasons over.
The determining factor is not how capable the model is. It is whether the feedback was interpreted before the model arrived.
Agents pull from support tickets, reviews, surveys, sales calls, and community threads in a single pass, which beats an analyst opening five tools. What an agent cannot do is notice what is missing. Connect only Zendesk and it will produce a well reasoned answer about your support backlog and present it as an answer about your customers. Canva ran this problem at scale, with feedback arriving in more than 100 languages across support, surveys, and reviews for over 220 million users. Breadth is the prerequisite, not a bonus.
Give a model ten thousand pieces of feedback and it will group them sensibly. Ask again next week with new data and the groups shift, merge, or rename themselves. This is inherent to generating structure at inference time, and it is the single biggest reason ad hoc agent analysis cannot support trend reporting. Notion's product ops team named the same thing from the other side: the advantage was not relying entirely on human categorization, and a generated taxonomy took their monthly user insights report from two weeks to three days.
Spotting a spike in a new complaint pattern is something agents do well and fast. Ranking that spike against everything else competing for the roadmap requires knowing who is complaining. An agent working from a flat feed has no way to distinguish a loud minority from a revenue concentration, so its prioritization reflects volume rather than impact. Apollo.io built its program around that link between feedback and revenue and cut its human inquiry rate by over 40 percent.
Agents write clean summaries. A summary with no traceable path back to source records is an assertion, and product decisions made on assertions get reversed the first time someone checks. Useful agent output carries citations down to individual pieces of feedback.
Natural language follow up is where agents earn their place: ask about a theme, drill into a segment, compare quarters, with no dashboard building in between. The failure mode is quiet. Independent testing of ticket-focused MCP setups found that when a question requires a specific metric definition or a large dataset, the model retrieves what fits and calculates from an incomplete sample without saying so.
Three approaches are on the market, and they fail in different places.
Survey-led platforms like Qualtrics and Medallia own structured collection and add text analytics on top. Strong when the question is about survey instruments and program governance. Weaker when most of your feedback never arrives as a survey.
Research repositories like Dovetail organize qualitative work for the people doing it. Excellent for a research team building evidence deliberately. Not built to compute across millions of unsolicited signals.
Text analytics tools like Thematic and SentiSum categorize open text at volume, often with support as the center of gravity. Good at the categorization job itself. The limit is usually how much of the account and revenue picture travels with the theme.
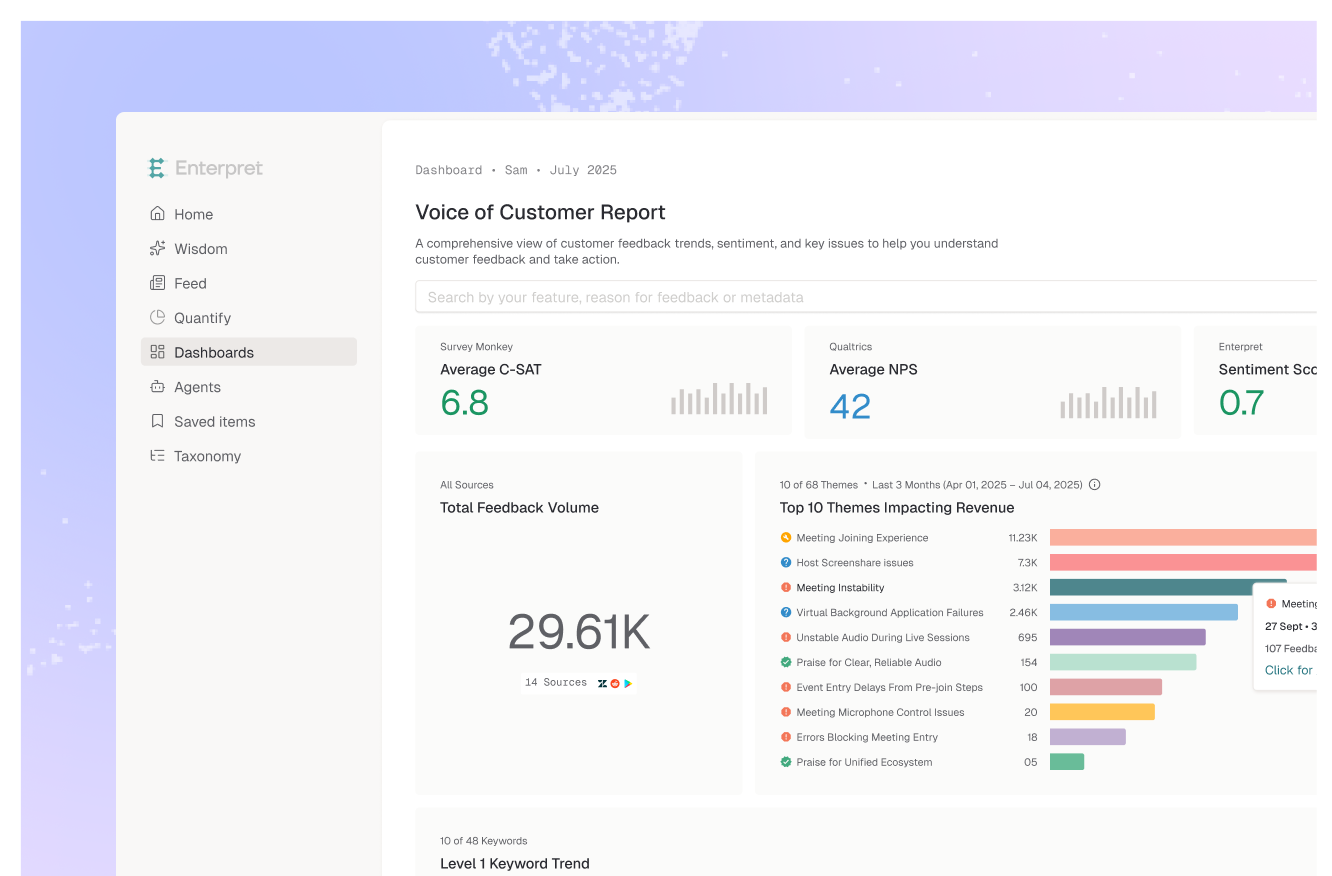
Enterpret sits in the fourth position: an intelligence layer built so the interpretation exists before any agent asks. An adaptive taxonomy learns categories from your own feedback rather than making you define them up front, and a customer context graph attaches account, segment, and revenue to every theme. The agent inherits both rather than rebuilding them per query.
"Can AI agents analyze customer feedback" treats the agent as the variable. Swap it: what is the agent analyzing?
An agent reading raw text does two jobs at once. It constructs a categorization scheme and reasons over it in the same breath, with no memory of the scheme it built last time. An agent reading feedback categorized at ingest only does the second job, and it does that job well.
That is the practical line between AI-assisted and AI-native feedback analysis. Assisted means pointing a model at your data and hoping. Native means the interpretation layer exists before the model arrives, so every query reasons over the same stable structure.
If you are exploring, prototyping, or working with a few hundred pieces of feedback, pointing an LLM at an export is fine and fast. Accept that the categories will not survive contact with next month's data.
If feedback informs roadmap or renewal decisions, the categorization needs to live outside the context window. Treat stable taxonomy, per claim traceability, and account level context as non negotiable, and treat the conversational interface as the layer on top rather than the product itself.
The decision rule: weight consistency across runs over impressiveness in a single run. Any model looks good on one query. Only a structured layer looks good on the hundredth.
They can handle the volume work unsupervised: retrieval, clustering, summarization, and follow up questions. Judgment calls about prioritization, tradeoffs, and what to build stay human. Most production programs are designed around that split deliberately rather than aiming for full automation.
Because they generate the categorization at inference time rather than reading a fixed one. Small changes in the input, the sample, or the phrasing produce different groupings, so the same dataset yields different themes across runs. A taxonomy built at ingest removes the variance.
Reasonably, on clear cases. Accuracy drops on sarcasm, mixed sentiment in a single message, and high intensity signals like cancellation intent, which practitioners consistently report as the most common limitation. Sentiment is more useful as a supporting dimension than as a standalone metric.
Enterpret categorizes feedback at ingest using an adaptive taxonomy learned from your own data, then ties each theme to the account, segment, and revenue behind it through the customer context graph. Agents query that structure rather than rebuilding it, so results stay consistent across runs and every claim traces back to source records.
Three things: whether every claim links back to specific records, whether the categories match what you saw last time you asked, and which channels were actually connected. A summary that fails any of the three is a hypothesis, not a finding.
If you are evaluating how agents should read your customer feedback, see how Enterpret's AI insights work over a structured intelligence layer.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.