



The 6 Differences Between Voice of Customer Software and Customer Intelligence

September 15, 2026

Knowing that forty customers asked for SSO is enough to rank a roadmap. It is not enough to do anything else with the decision. The CSM who needs to tell her accounts it shipped, the AE who wants to reopen a deal that stalled on it, and the PM who needs three design partners all need the same thing the count cannot give them: the list.
The five ways to get from a feature request theme to the named accounts behind it are querying the theme directly, filtering by account and segment attributes, tracing back through the source record, checking the channels where requests arrive unattributed, and maintaining the link as requests recur. The difference between them is mostly how much of the account context survives the trip from raw feedback to answer.
Most feedback tooling is built to aggregate. Requests come in, get categorized, and get counted, and the count is what appears in the roadmap review. That pipeline answers how many customers asked for this well enough.
The account list is harder because it requires the opposite motion. Aggregation deliberately discards identity to produce a number. Getting the list back means every individual piece of feedback has to stay joined to the account that produced it, through categorization and all the way to the query. Tools that treat feedback as a text corpus lose that join at the first step, which is why so many teams can produce a count in seconds and then spend a day in spreadsheets rebuilding the names.
The direct path, and the one that works only if the platform kept the join. Ask for the theme and request the account dimension as output rather than a chart.
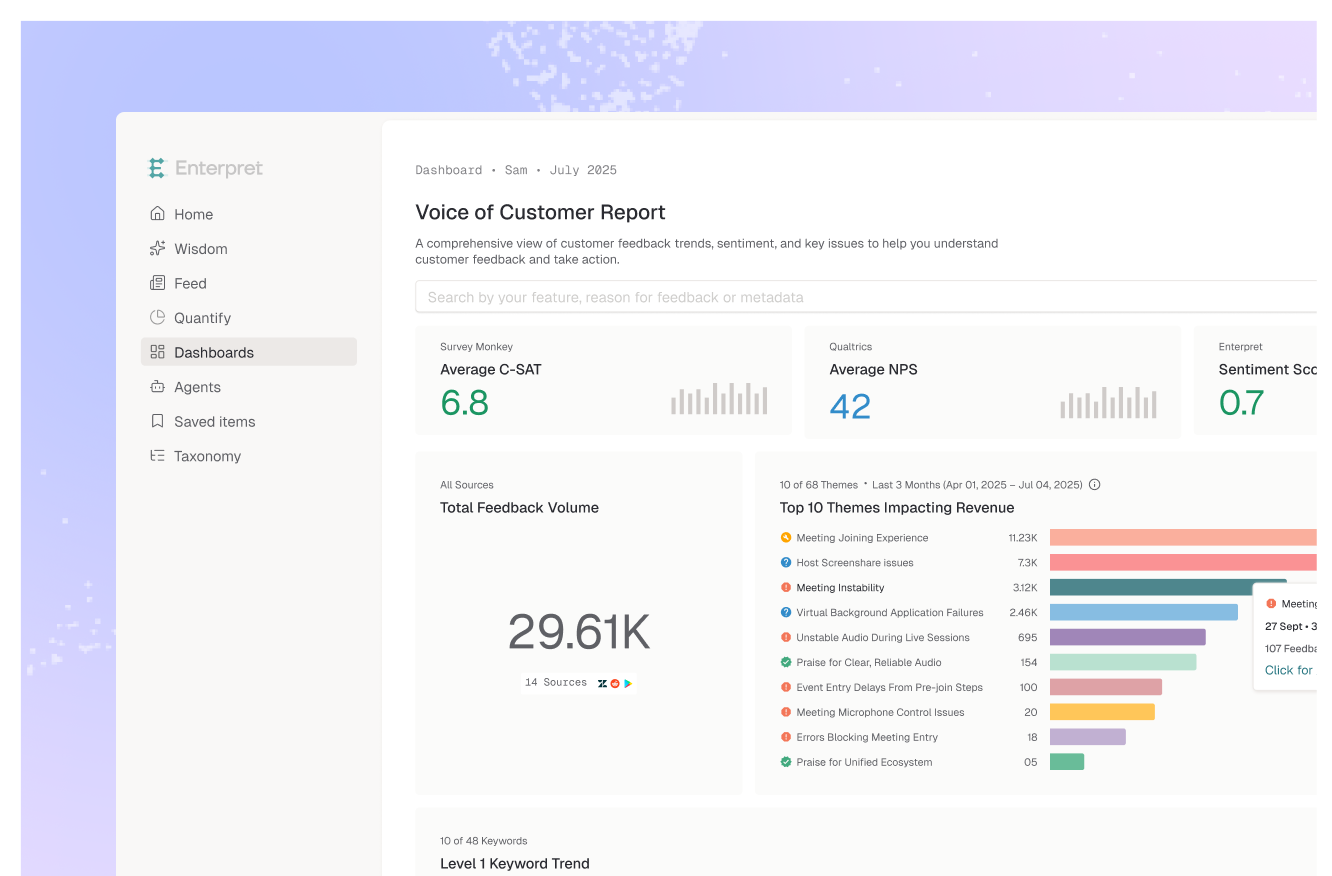
This is what a customer context graph is for: every categorized piece of feedback stays tied to the account, segment, and revenue behind it, so a theme can be expanded into its contributing accounts without leaving the tool. The useful output is not just names but names with ARR, plan, and the date each one asked, because that determines who gets contacted first.
Rarely is the raw list the actual question. What a PM usually wants is the enterprise accounts who asked, or the accounts on the plan where this feature would be gated, or the ones who asked more than once.
Filtering on segment, ARR band, renewal date, or region turns a list of forty into the six worth a conversation. This is also the step that exposes whether a request is broad-based or concentrated, which changes the build decision more than the raw count does.
When the platform cannot answer directly, the fallback is the source system: the Zendesk ticket, the Gong call, the community post. Each carries an author, and the author usually maps to an account.
This works but degrades badly at scale, because the mapping is manual and every channel maps differently. It is worth doing for a single high-stakes feature and not worth doing as a habit. If this is the standing process, the pipeline is the problem.
A meaningful share of requests arrive without an obvious account: app store reviews, anonymous survey responses, community posts under handles nobody has mapped, feedback relayed secondhand by a CSM.
These are invisible to account-level queries by default, and teams who ignore them systematically undercount enterprise demand, since enterprise users are often the ones posting under personal handles. Deciding explicitly how these get attributed, or accepting that they will not be, is better than discovering the gap mid-review. Detecting feature requests in support conversations covers the capture side of the same problem.
The list is not a one-time artifact. Accounts keep asking, new accounts join the theme, and some of the original requesters churn before the feature ships.
A standing view of the theme, refreshed as feedback arrives, is what makes the close-the-loop moment possible eighteen months later. This depends on categorization that does not need re-tagging every time the request is phrased differently, which is what an adaptive taxonomy provides by learning the categories from the feedback rather than matching fixed keywords.
If the platform holds account context natively, the first two ways are the whole job and take minutes.
If it does not, way three is the honest fallback for a single feature, and way four is the check that keeps the answer from being wrong in a predictable direction.
The decision rule: if producing this list is a recurring request rather than a one-off, fix the join rather than the query. Rebuilding account attribution by hand every quarter costs more than it looks like it does, and the answer gets less trustworthy each time.
The count supports a prioritization decision. The list supports an action: closing the loop, reopening a deal, recruiting design partners, or sizing revenue at risk. Most tools produce the first easily and the second with difficulty, because aggregation discards the identity the list requires.
Decide explicitly whether they count. Some teams attribute by email domain where available and exclude the rest, others treat unattributed volume as a separate directional signal. The failure mode is silently excluding them, which biases the answer against segments that tend to post under personal handles.
Yes, if the underlying feedback retained its account link and the categorization can be re-run over history. If requests were tagged manually against a fixed taxonomy, older phrasings often sit in the wrong bucket, and the historical list will be incomplete in ways that are hard to detect.
Enterpret categorizes feedback from 50+ channels with an adaptive taxonomy that learns the product's own categories, so requests phrased differently still land in the same theme. The customer context graph keeps every piece joined to its account, segment, and revenue, which means a theme can be expanded into the named accounts behind it along with the value they represent.
If producing an account list still means a spreadsheet, see how Enterpret ties customer feedback to the accounts behind it.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.