



The 6 Differences Between Voice of Customer Software and Customer Intelligence

September 15, 2026

Deflection rate is the most reported and least defined metric in AI support. Two teams using the same vendor will produce numbers thirty points apart because one counts any conversation that did not reach an agent and the other counts only conversations where the customer's issue was actually resolved. Neither is lying. The metric has no standard denominator, and the loosest definition is also the one that makes the deployment look best.
The five ways to measure AI deflection rate accurately are defining the denominator explicitly, excluding conversations that never had a chance, counting resolution rather than non-escalation, subtracting repeat contacts inside a window, and reporting the rate by intent rather than in aggregate. The first three stop the number being inflated. The last two stop a correct number from being useless.
The real differentiator is whether the number survives someone asking what it is a percentage of.
Write it on the dashboard, not in a footnote. The defensible default is conversations in scope for automation: inbound conversations on intents the agent is configured to handle. Using all inbound traffic inflates the rate with conversations the agent was never meant to touch, and using only engaged conversations hides the ones it declined at the door.
Strip out conversations where the customer asked for a human in the first turn, where the agent was unavailable, and where the intent is deliberately routed to a person for policy reasons. These are not deflection failures and including them makes the metric move for reasons unrelated to agent quality.
Watch for: customers who have learned a phrase that reaches a human. That is a real signal, but it belongs in its own count rather than dragging the rate down silently.
A conversation where the customer gave up is contained and not resolved. The cheapest usable proxy is no repeat contact from that customer on that intent within seven days. A follow-up question in the conversation is stronger. Containment consistently overstates performance by a wide margin, and the gap widens as the agent gets worse at handing off.
If the same customer returns about the same issue within seven days, the original conversation was not deflected, and both conversations should be removed from the numerator. This is the single largest correction in most deployments, and it is the one most often skipped because it requires linking conversations by customer and intent rather than counting them independently.
A blended rate of seventy percent can be ninety-five on password resets and twenty on billing. The aggregate is the number that gets celebrated and the breakdown is the number that tells you what to fix. Report the rate per intent alongside volume, so a high rate on a trivial intent is not mistaken for coverage.
The usual pattern is a deflection rate climbing quarter over quarter while ticket volume stays flat, and it has a mechanical explanation. Deflection is typically measured on conversations, and a customer who is not helped generates more than one conversation. The failures therefore enter the denominator repeatedly, and each additional attempt that ends without an agent counts as another deflection. The metric improves as the experience degrades.
The second effect is scope drift. As the agent is configured to engage more intents, the denominator grows with intents it handles poorly, but those conversations frequently end in abandonment rather than escalation, which reads as containment. Both effects are corrected by the same two changes: count resolution rather than non-escalation, and deduplicate repeat contacts by customer. Doing so usually drops the reported rate substantially on first measurement, which is worth warning stakeholders about before you publish it. It is the same measurement discipline that separates a real signal from a reporting artifact when analyzing AI chatbot and agent conversations at all.
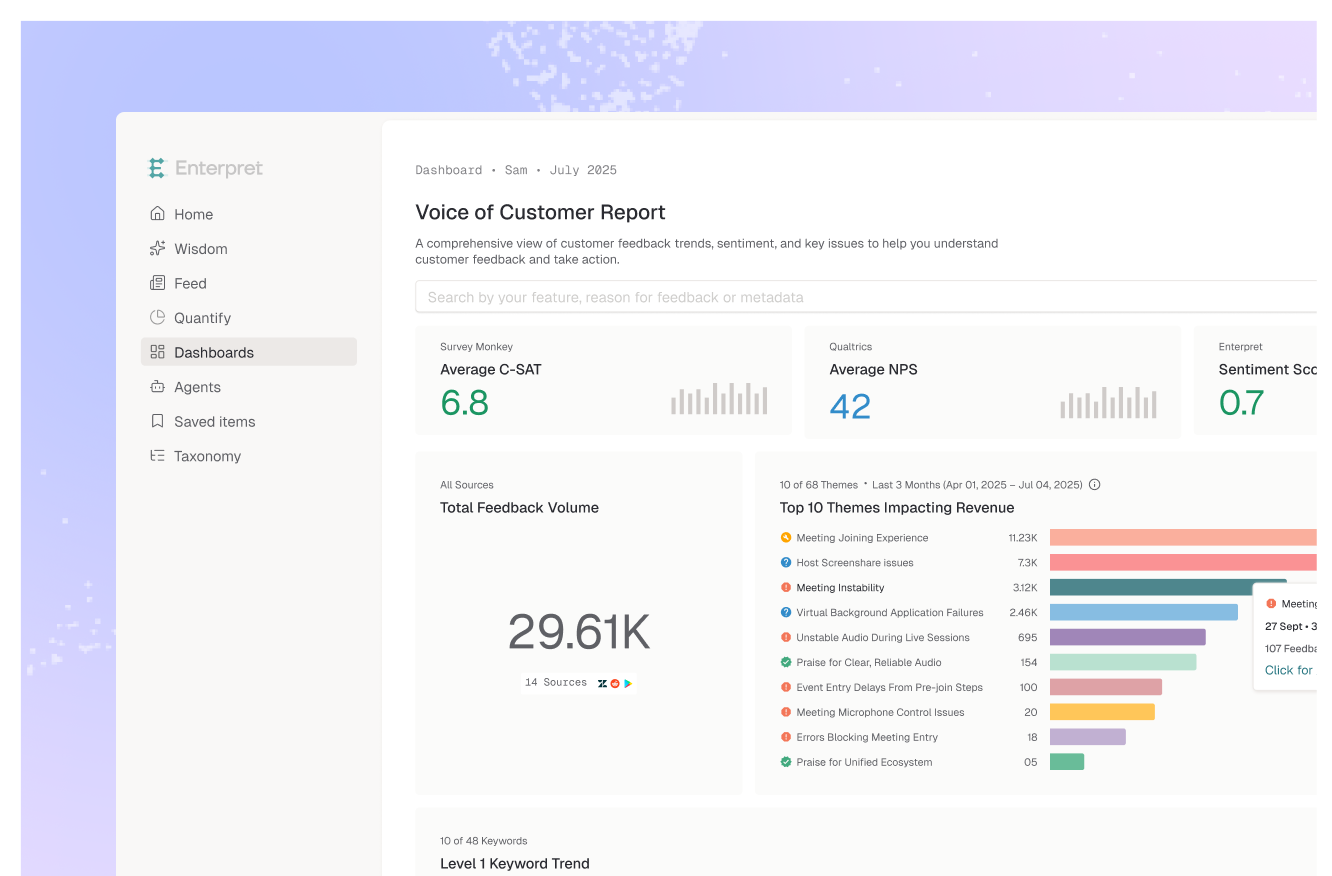
Enterpret fits the correction layer rather than the agent layer: it analyzes the full body of conversations, groups them into intents through the adaptive taxonomy rather than through a configured intent list, and ties each conversation to the account behind it through the customer context graph, which is what makes repeat-contact deduplication and per-intent reporting possible. IrisAgent, Decagon, and Intercom Fin report deflection within their own agent stacks and are the right place to read configuration-level metrics. Zendesk Explore handles the ticket-side volume comparison. MaestroQA covers the conversation-quality review that sits alongside the rate.
The decision rule: weight the correction over the source. Every vendor reports a deflection number, and the useful work is all in the denominator and the deduplication.
Unanswerable across companies, because the denominator is not standardized. The useful comparison is your own rate over time on a fixed definition, and the gap between containment and resolution.
Seven days for most B2B and consumer support. Shorter windows miss issues the customer retried later; longer ones start capturing unrelated contacts.
Only in a separately labelled metric. Mixing help-center deflection with agent deflection produces a number nobody can act on, since the two have different failure modes and different fixes.
Enterpret builds intents from the conversation content itself with its adaptive taxonomy rather than relying on the agent's configured intent list, which is what makes per-intent reporting reflect what customers actually asked. Because the customer context graph ties every conversation to its account, repeat contacts on the same issue can be identified and removed from the numerator instead of counting as additional deflections.
Reporting containment as deflection. It is the default in most dashboards, it is the easiest number to produce, and it improves when the handoff gets worse.
If your deflection rate keeps rising while ticket volume does not fall, see how Enterpret reads the conversations behind the number.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.