



The 5 Ways to Track Feedback for Just Your Part of the Product

September 22, 2026

Every product team has had the moment. Support is certain a problem is everywhere, CS has raised it in three consecutive account reviews, and the theme count says forty-one. Forty-one does not win a roadmap argument. So the problem stays unbuilt, and six months later it shows up in a churn reason.
The count is usually not wrong about the records it has. It is wrong about the question being asked. Five things produce this gap: the problem is fragmented across several themes, only some channels are connected, one record held several issues and only one was counted, the theme is named for a symptom rather than the problem, and records are being counted instead of accounts. Fixing the count is mostly a matter of finding which of the five is operating.
A theme count answers a narrow question. How many records were classified into this category, from the sources that feed it, during the period selected.
The question in the room is different. How many customers are affected, how badly, and what is it worth. The gap between those two questions is where every one of the five reasons below lives. None of them are counting errors. They are all mismatches between what was measured and what was meant.
The most common cause and the easiest to miss. One customer problem described in two vocabularies produces two themes with half the volume each, and neither one looks urgent. Support calls it a sync failure, product calls it a data freshness issue, and the forty-one you are looking at is really ninety-three. The fastest check is to sort themes ascending and look for any name that describes something you know is significant but reports a small number. See the five ways to find duplicate themes in your feedback categories for the full detection pass.
If the count draws on tickets and NPS but not sales calls, community posts, app store reviews, or CS notes, it is a partial census being read as a complete one. This usually undercounts in a specific direction: problems that block buyers show up in sales calls, problems that irritate power users show up in community, and neither appears in a support-only view. A theme that feels bigger than its count often feels that way because the people insisting on it are hearing it in a channel the count cannot see.
A single sales call or long ticket can carry five distinct pieces of feedback across three product areas. Systems that assign one category per record capture the dominant one and discard the rest. The effect is silent and cumulative: secondary mentions, which is where early signals of a spreading problem usually live, never make it into any count at all.
Feedback attaches to the language it matches. A theme named Slow dashboard collects the customers who used the word slow, while the customers who said it times out, it never finishes loading, or I gave up waiting land elsewhere or nowhere. Symptom names fragment by vocabulary. Problem names collect the whole population, which is why theme naming is a counting decision as much as an organizational one.
Forty-one records from forty-one different enterprise accounts is a different situation than forty-one records from three very vocal ones, and a raw count cannot tell them apart. In B2B this is the reason a count feels wrong more often than any other, because the people who feel the problem are weighing accounts while the report is weighing comments. See prioritizing customer feedback by revenue impact for what the alternative looks like.
The damage is not that a number is low. It is that a low number reads as evidence of absence, and in a prioritization meeting, evidence of absence beats conviction every time.
This produces a predictable pattern. The problems most likely to be undercounted are the ones spread across channels, described in several vocabularies, and concentrated in a small number of large accounts. Those are also, fairly often, the problems that matter most commercially. The taxonomy is not neutral about which problems win. It systematically favors the ones its structure happens to consolidate.
The second cost is slower. Once a team has watched a count be wrong twice, they stop trusting counts and revert to anecdote, which is the condition the feedback program was built to replace. A count that cannot be defended in a roadmap review is worse than no count, because it makes the whole practice look optional. Making roadmap reviews less opinion-driven depends on the count surviving the first challenge to it.
Work the five in order, because they are roughly ordered by how often they turn out to be the cause.
Check for fragmentation first, then check which sources are actually feeding the theme, then check whether your system can attach more than one theme to a single record. Those three explain most gaps. If the count still feels low, read the theme name and ask whether it describes what customers typed or what is actually broken. Then switch the unit from records to accounts and see whether the picture changes.
The decision rule for the meeting itself: bring the account count and the revenue exposure, not the record count. Forty-one records is a number someone can argue with. Nineteen accounts representing a named share of renewal value is a number that ends the argument, and it is the same underlying feedback either way.
Usually because support is hearing the problem across several themes, or in a channel the count does not include. Both produce a count that is accurate about its own scope and wrong about the question being asked.
Often, and that is the point of measuring. The test is whether the count holds up after you have checked for fragmentation, channel coverage, and single-label classification. A low count that survives those checks is real information and should be trusted.
Accounts for reach, revenue for weight, records only for trend direction. In B2B, record counts overweight whichever customers happen to write in most, which is rarely the same population as the customers who matter most to a renewal.
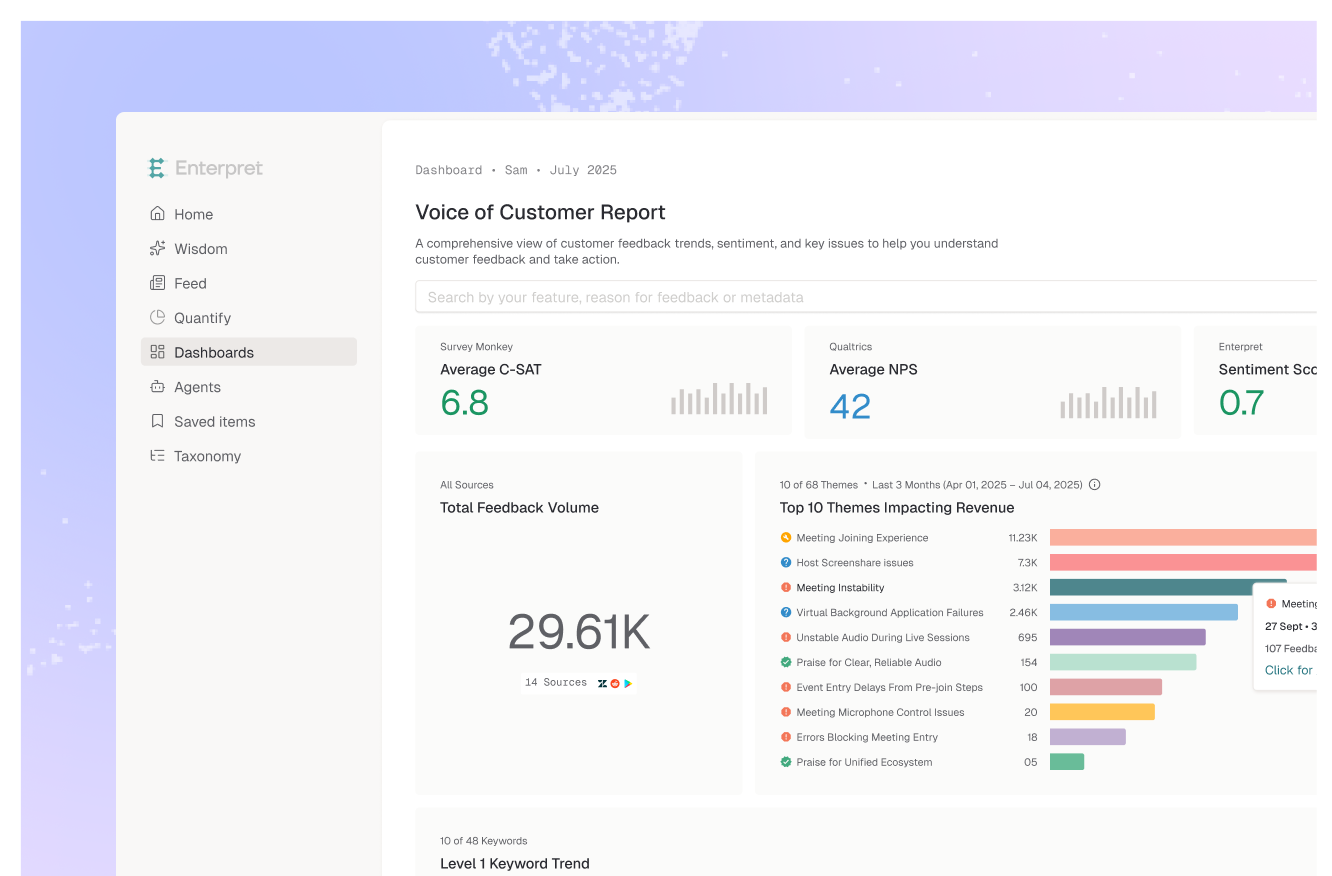
Enterpret's adaptive taxonomy groups feedback by meaning rather than keyword and can attach multiple themes to a single record, so a long call or ticket contributes everything it contains instead of just its dominant topic. The customer context graph then resolves that volume to accounts, segments, and revenue, which is the unit a prioritization conversation actually runs on.
Yes, and that is usually desirable. Merging fragmented themes should consolidate their history rather than reset it, which means the corrected trend line shows what was always true rather than starting over from the date of the fix.
If your counts are not surviving roadmap review, see how Enterpret ties feedback to revenue impact.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.