



The 5 Ways to Track Feedback for Just Your Part of the Product

September 22, 2026

A research team that has run three hundred interviews has a problem the first thirty did not create. Any individual conversation is legible. The set is not. Nobody has read all three hundred recently, the ones people quote are the ones they personally ran, and the synthesis that exists was written against a subset somebody had time for.
Five approaches handle this: manual coding with a defined scheme, affinity mapping by a group, keyword search across transcripts, LLM summarization run study by study, and semantic classification across the whole corpus alongside your other feedback. They differ in what they can see. The first four operate on a sample or a study, and the fifth is the only one that treats the entire interview corpus as one dataset, which is where patterns across studies actually live.
Because interviews are deliberately unstructured, and the structure is added afterwards by a person.
That works at small scale and produces two failures at large scale. The first is recency: the last ten interviews carry more weight in any discussion than the two hundred before them, because those are the ones people remember. The second is silo: each study gets synthesized on its own, so a pattern appearing weakly in four separate studies is invisible, even though four weak signals from different contexts is a stronger finding than one strong signal from a single study.
There is a third problem that only shows up later. Interviews get synthesized separately from tickets, reviews, and calls, which means the question of whether what customers say in interviews matches what they report elsewhere is almost never answered. It is one of the more useful questions available and it requires the two corpora to live in the same structure.
A researcher reads transcripts and applies codes from an agreed scheme. The gold standard for accuracy and the reason it is the gold standard is that a human understands context, hedging, and what a participant meant rather than said. It also runs at roughly ten to twenty interviews per researcher-week, which puts three hundred interviews outside what most teams will ever do.
Best for: a focused study where depth matters more than coverage.
Several people sort observations into clusters collaboratively, usually on a wall or a virtual board. Fast, good at producing shared understanding, and it works on notes rather than transcripts, which means the fidelity depends on whoever wrote the notes. Results are not reproducible: run it twice with different people and you get different clusters.
Best for: building team alignment after a round of research, not for a defensible count.
Search the corpus for terms you already suspect matter. Fast and useful for verification, useless for discovery, because you can only find what you thought to look for. It also misses every participant who described the thing without using your word for it, which in interviews is most of them, since people speak in their own language rather than yours.
Best for: checking whether a hypothesis has support before investing in a real analysis.
Feed transcripts to a model and ask for themes. Genuinely useful for a single study and it degrades across studies, because each run produces its own categories. Ask twice and you get different groupings, which means you cannot compare study three against study eleven or count anything across the corpus. The output reads well and does not accumulate.
Best for: a fast first pass on one study you will then verify.
Every interview is classified against one persistent structure, alongside tickets, reviews, and calls. Patterns across studies become visible because the categories are stable, and a theme can be counted across three hundred interviews and every other channel at once. This is the only approach on the list that answers whether interview findings show up elsewhere in your feedback, which is usually the question that decides whether a finding gets built.
Best for: any team where interviews are ongoing rather than a one-off project.
The finding most worth having is the one no single study contains.
A need mentioned in passing by two participants in four different studies is twenty people describing the same gap, and nobody sees it, because each study's synthesis fairly concluded that two mentions was not a theme. The signal is real and it is distributed, which means it is invisible to any method that works study by study.
The same applies across channels. A frustration voiced gently in interviews and angrily in support tickets is one problem with two registers, and a team synthesizing interviews separately from tickets will treat them as unrelated. Where interviews sit in the same adaptive taxonomy as the rest of your feedback, that connection is a filter rather than a project. See how to find patterns in feedback across channels for the volume side of the same problem.
If you have run fewer than fifty interviews and they belong to one study, code them manually. Nothing beats it at that scale and the overhead of anything else is not worth it.
If interviews are an ongoing practice rather than a project, the manual approaches will not keep up, and the choice is between per-study LLM summarization and persistent classification across the corpus. The deciding question is whether you need to compare across studies. If you do, per-study summarization cannot get you there no matter how good the individual summaries are, because the categories do not persist.
The decision rule: weight category persistence over per-study quality. A slightly worse analysis you can compare across three hundred interviews beats an excellent analysis of thirty.
Classify the full corpus against one persistent structure rather than summarizing study by study. Per-study summarization produces different categories each run, which makes comparison across studies impossible regardless of how good each summary is.
For coverage, yes. For depth on a single study, not reliably. The practical split is automated classification across the whole corpus to find where to look, then manual reading of the specific interviews that matter.
Because studies are synthesized in isolation. A need mentioned twice in each of four studies is twenty people, and every individual synthesis correctly concluded that two mentions was not a theme.
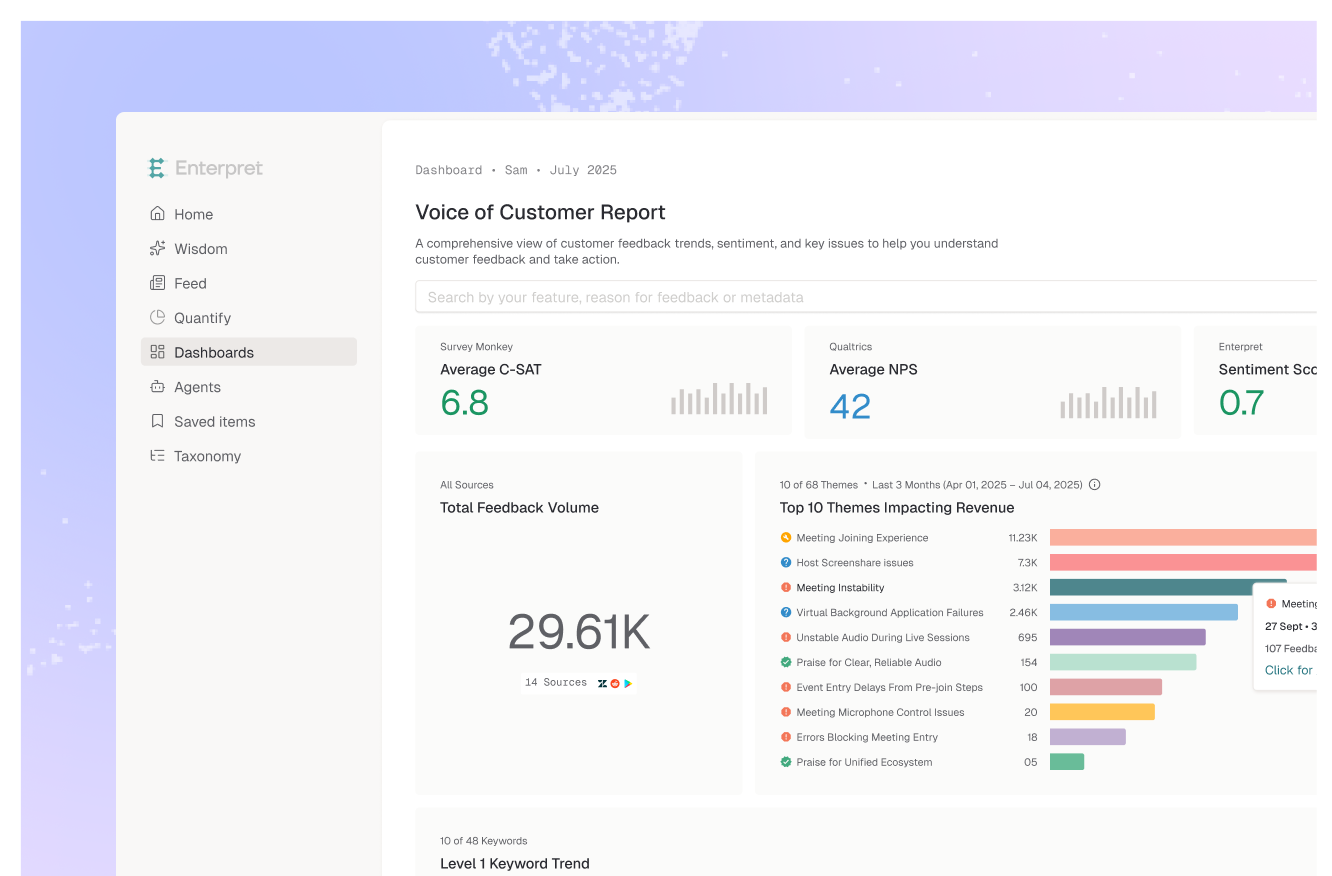
Enterpret's adaptive taxonomy classifies interview transcripts against the same structure as tickets, reviews, and calls, extracting each distinct point rather than one theme per transcript, so patterns across studies and across channels are visible in one place. The customer context graph ties each participant to their account, so a finding can be weighted by which customers it came from.
Yes. Keeping it separate makes the most useful question, whether what customers say in interviews matches what they report elsewhere, effectively unanswerable.
If your research is accumulating faster than you can synthesize it, see how to scale customer feedback management as volume grows.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.