



The 6 Differences Between Voice of Customer Software and Customer Intelligence

September 15, 2026

Adoption at 40% with complaint volume on the original problem flat is not a successful launch. It is a feature that got clicked. Most post-launch reporting stops at the first number and never asks the second one, which is how teams end up defending a launch that technically worked and demonstrably did not help.
The six metrics that make a post-launch read honest are: eligible-population adoption, complaint volume on the original problem, net-new friction, time-to-first-value, adoption by segment and revenue, and the requests the launch did not close. The first four are measurable within 30 days. The last two are what separate a launch report from a launch announcement.
The product analytics category has done a good job on the telemetry half of this. Reach, adoption, engagement, retention, revenue impact: those ladders are well documented and worth running. What telemetry cannot tell you is whether the pain the feature was built to solve went away.
That is a different data source. Adoption comes from events. Relief comes from feedback. A team that only instruments events will see 40% adoption and call it. A team that also reads the complaint volume on the driver behind the build will see whether the number moved, and sometimes it does not, and that is the finding.
The permutation that matters: adoption high plus complaints down is a win. Adoption high plus complaints flat is a usability or scope miss. Adoption low plus complaints down means something else fixed it. Adoption low plus complaints flat means you shipped the wrong thing. Four outcomes, four different next sprints.
Percentage of accounts that could use the feature and did, not percentage of all actives. Define eligibility before launch: the plan tier, the workflow, the segment. Report both the eligible-population number and the raw number, because the gap between them is itself diagnostic.
The relief metric, and the one that almost never appears in launch dashboards. Take the feedback category that justified the build, count it for the 30 days before ship, count it for the 30 days after, and normalize for volume growth. If it did not move, the feature did not solve the problem, no matter how many people opened it.
Themes that did not exist before the launch and do now. Every shipped feature creates some. The question is whether the new friction is smaller than the friction removed. Track first-seen date and slope, not just count, because a theme going from zero to steady in two weeks matters more than one that spiked on launch day and decayed.
How long between an eligible account's first exposure to the feature and their first completed use of it. This is the metric that tells you whether the problem is discovery or the feature itself. A long time-to-first-value with high eventual adoption is a discovery bottleneck. A short one with low adoption is a value bottleneck. Different fixes.
The same adoption number, split by the segments that generated the original demand. Launches routinely land with the wrong cohort. Knowing that within 30 days changes the next thing you build. See validating a feature request before you build it for catching this before ship rather than after.
Every feature ships against a cluster of requests and closes some subset of them. List the remainder explicitly: who asked, what they asked for, and whether the shipped version covers it. This is the input to the next iteration, and it is also your close-the-loop list. See telling requesters their feature shipped.
Most teams run one review at day 30 and stop. Day 30 tells you about reach and adoption. It is too early for retention and far too early for business impact, and it is also too early for the relief metric, because complaint volume lags: customers who already worked around the problem do not immediately stop complaining about it, and customers who hit the new friction have not all hit it yet.
Run three reads. Day 14 for adoption and net-new friction, which is when the fast fixes are still cheap. Day 30 for time-to-first-value and segment split. Day 60 for relief, which is the first honest read on whether the complaint volume actually moved. Killing a feature on the day-30 number is the most common post-launch mistake, and it is usually a measurement error rather than a product one.
Worth naming the bottleneck honestly: the relief metric is the hard one, because it requires that your feedback was categorized consistently before you knew you would need it. That is a data-infrastructure decision, not a reporting one, and it is made months before the launch. See product feedback software that connects feedback to release planning and best customer feedback tools for beta releases.
Instrument the events before the announcement, not after. Define the eligible population and the complaint category in the launch brief, so the denominator and the baseline are agreed before anyone has an incentive about the result. Set the three read dates on the calendar at ship. Assign one owner for the day-60 relief read, because it is the one that gets skipped.
The decision rule: if adoption and relief disagree, believe relief. Adoption measures whether you built something people found. Relief measures whether you built the right thing.
Adoption against the eligible population, complaint volume on the original problem before and after, net-new friction themes, time to first value, adoption split by segment and revenue, and the requests the launch did not close. Telemetry covers the first, fourth, and fifth. The others require feedback data.
Three reads: day 14 for adoption and new friction, day 30 for time-to-value and segment split, day 60 for whether complaint volume on the original problem actually fell. A single 30-day read is the most common cause of features being killed or declared successful too early.
Count the feedback category that justified the build for a fixed window before ship and the same window after, normalized for overall volume growth. If the category does not decline, the feature did not solve the problem regardless of adoption. This only works if the category was stable before the launch.
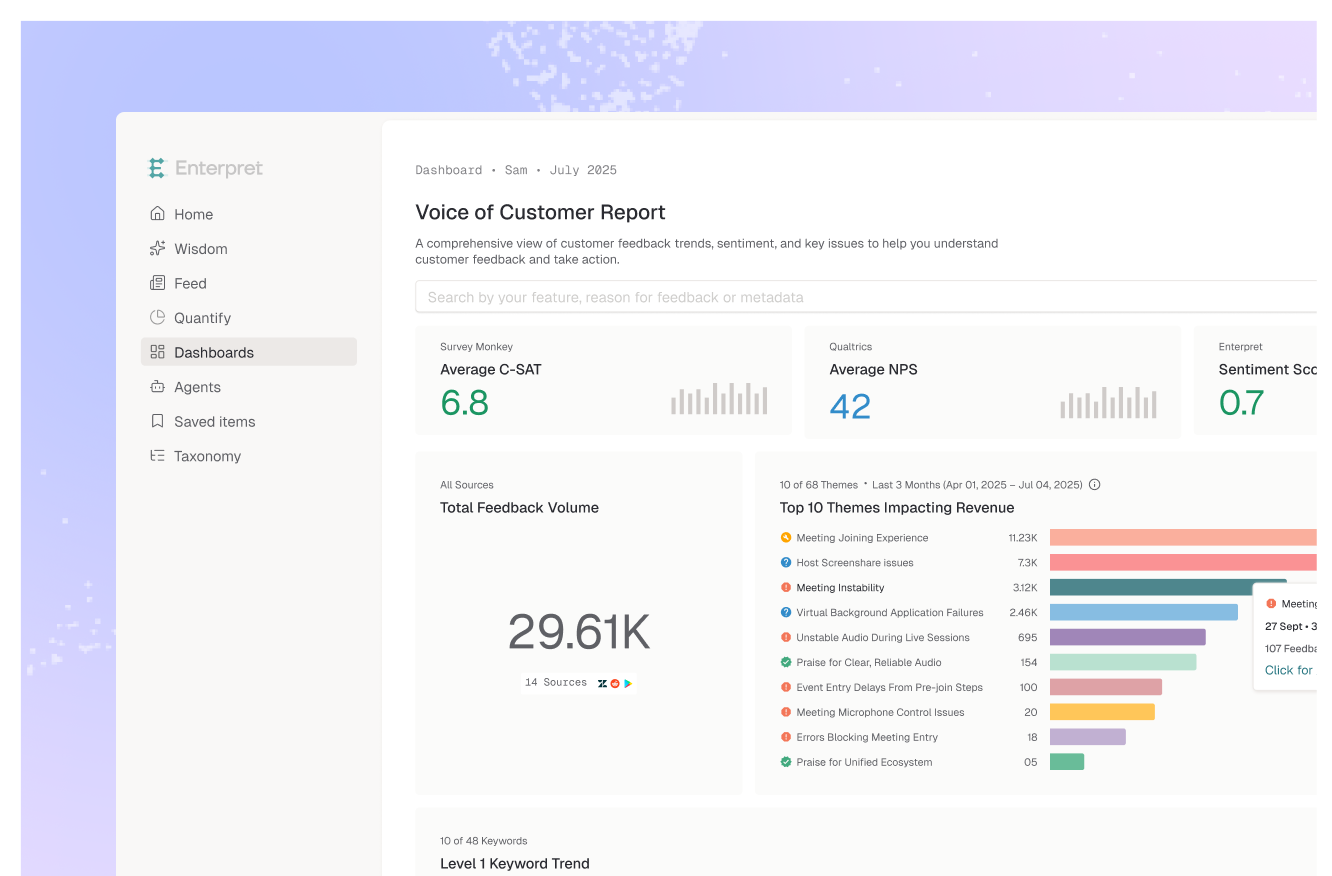
Enterpret categorizes feedback from tickets, reviews, surveys, calls, and community channels using an adaptive taxonomy that learns your product's structure from the data, so a complaint category stays comparable across a launch boundary instead of breaking when new vocabulary arrives. The customer context graph ties that feedback to the accounts and revenue behind it, so you can see whether the segment that asked for the feature is the one now using it. A launch monitor can run as a scheduled job for the weeks after ship.
It is necessary and not sufficient. Adoption tells you the feature was discoverable and at least minimally useful. It cannot tell you whether the problem it targeted eased, whether it introduced new friction, or whether it landed with the cohort that asked. Pair it with the relief metric or it will mislead you.
Running a launch and want the feedback side of the read? See how Enterpret handles product feedback analysis. Try it against your next ship and see where the model breaks.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.