



Enterpret Alternatives and Competitors in 2026: How the Top Platforms Compare

September 25, 2026

An AI support bot quality audit template should cover seven checks: answer accuracy, handoff quality, repeat contact after the bot, false containment, customer sentiment about the bot, coverage gaps, and impact by customer segment. Each check needs four fields: a metric, an evidence source the bot does not control, a condition that flags it, and an owner. The copy-ready template is below.
The reason for the evidence-source field is simple. A bot's own dashboard grades its own work. Containment rate records a conversation as handled when the customer stops replying, and a customer who gives up stops replying too. A useful audit measures what the customer did next: whether they came back, switched channels, complained somewhere else, or left.
Copy this table into a spreadsheet or doc and set your own targets for each flag condition. Compare every metric against human-handled conversations on the same intent so the audit isolates the bot's performance from the mix of questions it receives.
| Check | What to measure | Evidence source | Flag when | Owner |
|---|---|---|---|---|
| 1. Answer accuracy | Share of sampled bot answers that match current policy and documentation | Weekly sample of bot transcripts reviewed against the knowledge base | Accuracy falls below target, or any answer contradicts a policy | Support QA lead |
| 2. Handoff quality | Whether the bot hands off when it should, and whether the human receives the context | Escalated conversations, time to human, customer restating the issue | Customers repeat their problem after handoff, or handoffs arrive without context | Support operations |
| 3. Repeat contact after the bot | Same customer, same issue, contacting again within 7 days of a bot-resolved conversation | Tickets, chat, email, and calls joined to the same customer | Repeat contact rate for bot-resolved issues exceeds the rate for human-resolved issues | Support operations |
| 4. False containment | Conversations counted as contained where the customer abandoned rather than got an answer | Conversations that end without confirmation, followed by another channel or a cancellation | Abandonment rises week over week for an intent | Support QA lead |
| 5. Sentiment about the bot | What customers say about the bot inside and outside the conversation | Bot transcripts, CSAT comments, reviews, social posts, and sales and CS calls | Negative mentions of the bot rise in any channel | CX insights |
| 6. Coverage gaps | Questions the bot cannot answer or answers from outdated content | Unresolved intents, fallback responses, and escalations grouped by topic | A new topic appears in fallbacks or escalations | Knowledge and content owner |
| 7. Impact by customer segment | Where bot failures concentrate by plan, segment, lifecycle stage, and account value | Bot conversation outcomes joined to CRM and account data | Failures concentrate in high-value segments or accounts near renewal | CX leader and account owners |
Accuracy is the baseline check and the one most teams already run. Review a fixed weekly sample of bot answers against current policy, pricing, and documentation, and score each answer as correct, partially correct, or wrong. Track wrong answers by intent, because a bot that is accurate overall can still be consistently wrong on refunds or billing.
A bot that escalates at the right moment is working as designed. The failure is a late handoff, or a handoff where the human agent starts from zero. Measure how often customers restate their issue after the handoff and how long they wait for a person.
This is the most reliable signal that a bot did not resolve anything. If a customer returns within seven days about the same issue, the first conversation was not a resolution, whatever the bot recorded. Compare the repeat contact rate for bot-resolved conversations against human-resolved ones on the same intent.
Containment counts a conversation as handled when the customer stops replying, which is also exactly what a frustrated customer does. Separate confirmed resolutions from silent endings, then check what the silent-ending customers did next: another channel, a refund request, or a cancellation.
Customers rarely tell the bot it failed. They say it in a CSAT comment, an app store review, a social post, or to their account manager on a call. An audit that reads only bot transcripts misses the strongest evidence, so this check has to span every channel where customers talk about support.
Group fallback responses and escalations by topic every week. A topic that appears suddenly usually means a launch, a policy change, or an outage the knowledge base has not caught up with. Each gap becomes a content task with an owner.
A bot failure on a free-plan password reset and the same failure on an enterprise account near renewal are not the same problem. Join bot outcomes to plan, segment, lifecycle stage, and account value so the audit shows who is affected, not just how often.
Weekly: review a fixed sample of bot transcripts for accuracy and handoff quality, and scan fallbacks for new topics.
Monthly: run all seven checks, including repeat contact, false containment, sentiment across channels, and segment impact, and compare each against the human-handled baseline.
After every change: rerun the accuracy and coverage checks whenever the bot's model, prompts, or knowledge base changes. Regressions cluster around changes.
Keep the categories identical for bot and human conversations. If the bot's intents and the support team's ticket tags use different labels, the comparison breaks and the audit turns into a translation exercise.
Checks 1 and 2 can live inside the bot platform. Checks 3 through 7 cannot, because the evidence sits in other systems: the ticket queue, call recordings, reviews, and the CRM. That is where Enterpret fits.
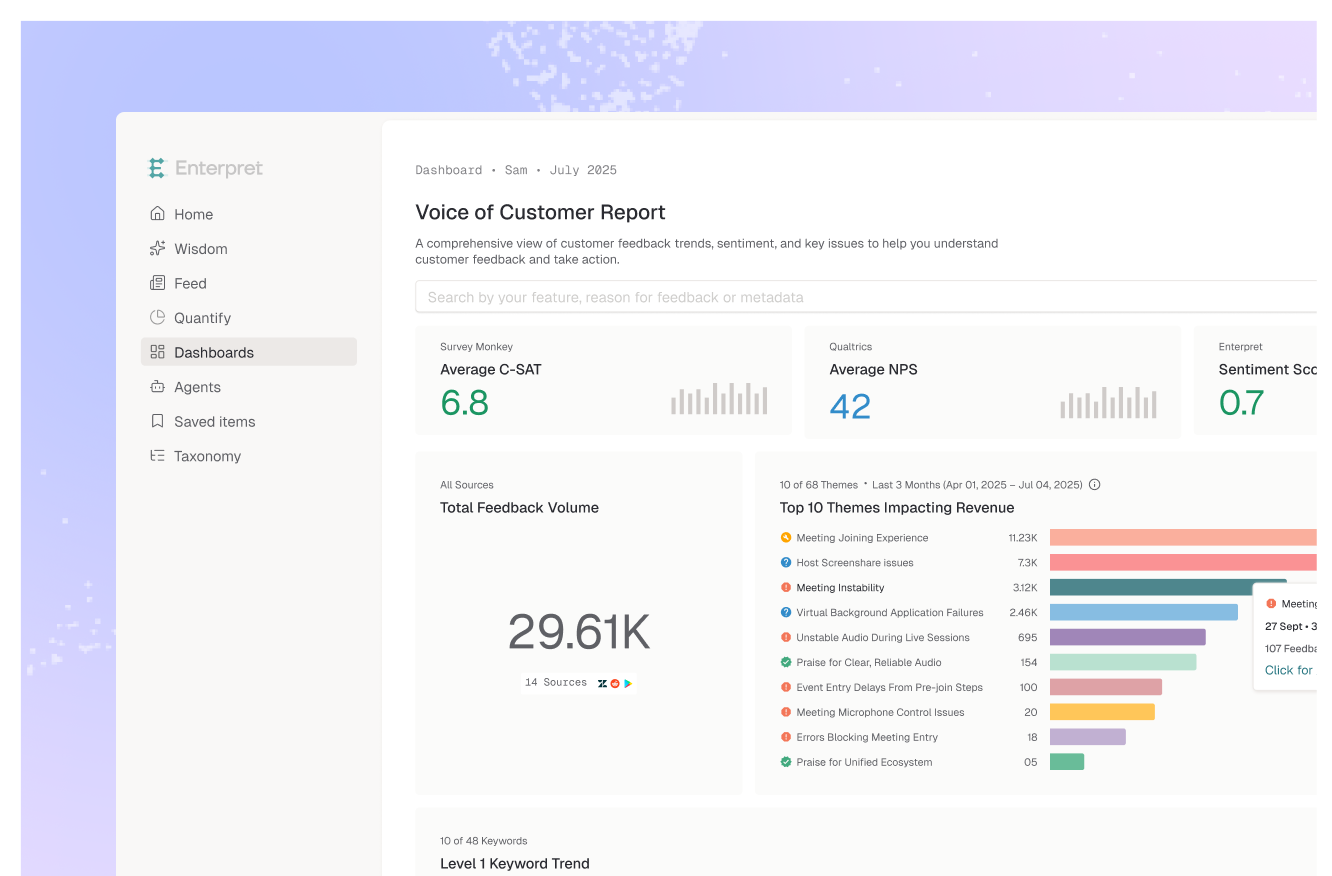
One taxonomy for bot and human conversations. Enterpret ingests AI agent conversations, such as those from Decagon, alongside Zendesk and Intercom tickets, calls, surveys, and reviews. The Adaptive Taxonomy classifies all of them into the same themes and evolves with customer language, so bot and human performance are comparable issue by issue.
Segment and account context on every conversation. The Customer Context Graph attaches segment, LTV, lifecycle stage, and usage to every signal, which is what check 7 needs and what bot dashboards do not have.
Agents that run the checks continuously. Enterpret's AI agents detect negative sentiment shifts in support threads, flag high-escalation-risk feedback, analyze agent-level CSAT for coaching, identify recurring questions not covered by existing help content and draft improvements, and convert critical feedback into tracked issues in Jira and Linear.
An AI support bot quality audit should include seven checks: answer accuracy, handoff quality, repeat contact after the bot, false containment, customer sentiment about the bot, coverage gaps, and impact by customer segment. Each check needs a metric, an evidence source outside the bot's own dashboard, a flag condition, and an owner.
Run a sampled review weekly, a full audit monthly, and an extra review after every change to the bot's model, prompts, or knowledge base. Changes are when regressions appear, so they deserve their own checkpoint.
Containment counts a conversation as handled when the customer stops replying, which also happens when a customer gives up. Repeat contact, abandonment followed by another channel, and sentiment outside the bot conversation show whether contained conversations were actually resolved.
Use the same categories and the same metrics for both. Compare repeat contact, escalation, and sentiment for bot-handled and human-handled conversations on the same intent, so differences reflect the bot rather than the mix of questions it receives.
Enterpret ingests AI agent conversations, such as those from Decagon, alongside tickets, calls, reviews, and surveys, and classifies all of them with the same Adaptive Taxonomy so bot and human performance are comparable by theme. The Customer Context Graph attaches segment, LTV, and lifecycle stage to every conversation, and Enterpret's AI agents monitor sentiment shifts, flag escalation risk, and draft help content for coverage gaps.
Related reading: the metrics every support team scorecard should track and the signals that customers do not trust your AI feature.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.