



The 6 Steps to Build a Multi-Level Customer Feedback Taxonomy

September 30, 2026

Yes. A well-built AI-generated feedback taxonomy is inspectable at every level, editable by the team that owns it, and traceable back to the individual customer verbatims behind every theme. The systems where that is not true are the ones worth avoiding, and the distinction is the single most useful thing to test during an evaluation.
The reason the question comes up so often is that "AI-generated" and "black box" have become synonyms in a lot of buying conversations. They are not the same thing. A taxonomy can be derived automatically from your data and still expose every decision it made. What separates the two is not whether a model built the structure. It is whether the system was designed to show its work, and whether anyone checks the structure as a whole. Enterpret research found that AI-generated taxonomies can pass every standard node-by-node check while failing in ways only a whole-tree view reveals.
It is one of the detailed guides in how to maintain a customer feedback taxonomy, which includes a governance checklist.
The question hides three different concerns, and they have different answers.
The first is traceability. Can you click a theme and see the raw feedback inside it? This is the baseline. A theme that says 412 customers raised a login issue is a number you have to take on faith unless you can open it and read the 412 records.
The second is inspection. Can you see the structure itself, the full hierarchy of categories, how they nest, and which ones the system created recently? A taxonomy you cannot view is a taxonomy you cannot reason about.
The third is correction. When the system gets something wrong, and it will, can you fix it? Can you merge two themes that mean the same thing, split one that is doing too much work, rename a label your team finds confusing, or move a category to a different parent?
Most vendors answer the first question well and get vaguer on the second and third. Ask about all three separately.
These are worth scoring any platform against, including ours.
The fourth is where most systems separate. Correcting an output is easy. Correcting the model that produced it is the harder engineering problem, and it is the one that determines whether the taxonomy stays accurate over a two-year horizon rather than a two-week one.
Auditing is not a single activity. Five methods answer different questions, cost different amounts, and catch different failures. Most teams run one of them and assume they are covered.
The pairing that works for most teams is a spot check before any decision and structural diffing on a cadence. Run whole-tree checks once after any taxonomy is generated or regenerated, since that is when structural failures are introduced. Sampling earns its cost before a board-level number and rarely more often than that. Running none of them and trusting the counts is the common default, and it holds until the first time someone asks why a theme doubled.
The evaluation checklist further down is for choosing a platform. This is the recurring version, for a taxonomy already in production.
Quarterly is enough for most teams. Tie it to a cadence that already exists, since an audit with no owner and no calendar slot does not happen. The symptoms that mean yours is overdue are covered in signs your feedback taxonomy needs a review.
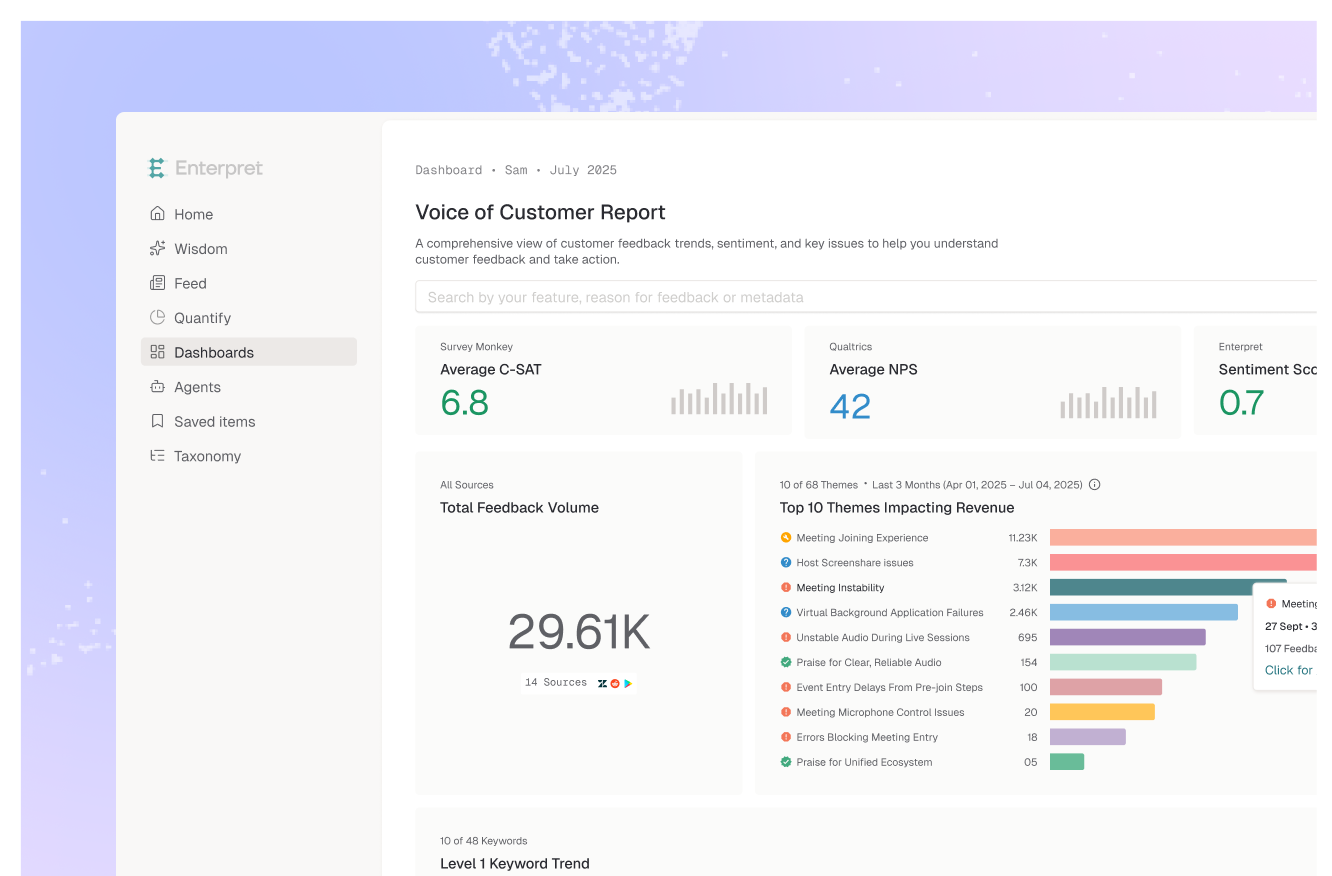
Enterpret's adaptive taxonomy is a hierarchical structure built from your own feedback rather than from a codeframe you design up front. It organizes into product area, feature, and sub-feature levels, plus themes and sub-themes that carry the reason behind the mention.
Every level of that structure is visible and editable. Keywords and themes can be refined inline, and the refinements carry an audit trail, so a correction is a recorded decision rather than an untracked change. Those refinements also tune future classification, which is the persistent-correction property above. You are adjusting the system, not relabeling a report.
Traceability runs all the way down. Any theme opens to the records inside it, and each record carries the account, segment, and revenue behind it through the customer context graph. That matters more than it sounds for audit purposes. When someone challenges a theme, the useful defense is rarely the total count. It is being able to say which accounts are in it and what they are worth.
The onboarding step is where day-one accuracy gets set. Help docs, changelogs, and historical feedback get ingested so the model learns your acronyms and internal product names before it starts classifying, which reduces the volume of corrections you have to make later. More on the mechanics in AI-generated feedback taxonomy.
A learned taxonomy gives you less control over exact label wording than a hand-built codeframe. That is the design intent, not an oversight, but it is a real difference and worth knowing if your team is attached to a specific scheme or has a taxonomy that maps to a regulatory or reporting standard you cannot change.
The comparison to run is not control versus no control. It is where the control costs you something. A manually maintained codeframe gives you total naming authority and charges you a recurring maintenance tax that compounds with volume and with every product launch. An adaptive structure gives you override authority and absorbs the maintenance. Teams with a dedicated analyst who wants to own theme definitions line by line often prefer the first. Teams whose feedback volume is growing faster than their headcount almost always end up needing the second.
Analyst-led platforms like Thematic build their positioning around human curation of the theme structure, and for insights teams with the headcount to do it, that is a legitimate choice rather than a weakness. The question is which constraint binds first in your organization: naming precision, or the person-hours to maintain it.
Run it on your own data, not on a demo dataset. Then do four things in the trial account.
Open a theme and read the records inside it. Find a classification you disagree with. Correct it, and check whether the correction holds on new feedback the following week. Then look at whether the change is recorded anywhere you could point to in three months when someone asks why a number moved.
If all four work, the taxonomy is auditable regardless of how it was generated. If any of them requires a vendor ticket, you are looking at a reporting layer rather than a system you own.
Then ask for two whole-tree numbers, or measure them yourself if you can export the hierarchy: the share of leaf labels that restate a parent, and the share of records that land in more than one top-level area. Neither shows up in a demo. In Enterpret research, two runs of the same AI agent produced taxonomies that standard checks rated as comparably correct, and the second of those numbers separated them by 27 points.
Yes. A taxonomy is auditable when four things are true: every theme opens to the records inside it, the category hierarchy is visible, structural changes are recorded, and the team can correct classifications without a vendor request. Those properties depend on how the system was built rather than on whether a model generated the structure, so ask about each one separately during an evaluation.
Yes, in any well-designed system. You should be able to merge duplicate themes, split themes doing too much work, rename labels, and move categories within the hierarchy. The more important test is whether the edit persists, meaning future feedback classifies against your correction rather than reverting to the original label.
It should not be. Adaptive describes how the structure is created, from your data rather than from a predefined list. It says nothing about whether the structure is visible. Ask specifically about hierarchy visibility, record-level traceability, and whether corrections carry an audit trail, since those are the properties that determine transparency.
Open it and read the records. Accuracy in feedback classification is not a single score, it is whether the specific theme you are about to act on contains what it claims to contain. Spot-check the themes that are driving decisions rather than trying to validate the whole taxonomy at once.
Quarterly suits most teams, with a spot check before any individual decision that rests on a theme count. The trigger for an unscheduled audit is a volume change you cannot explain, since the first question about a theme that doubled is whether customer behavior changed or the category boundary did.
An adaptive taxonomy absorbs new themes automatically as customer language shifts, which is the main advantage over a fixed tag list that has to be extended by hand after every launch. The thing to watch is drift in existing definitions, which is why structural change visibility belongs in the evaluation criteria above.
The adaptive taxonomy learns from your feedback continuously and incorporates inline refinements into future classification, so accuracy improves rather than decays. Each classified record stays tied to its account, segment, and revenue through the customer context graph, so a theme can always be verified against who actually said it and what they are worth. Related reading on the mechanics: automate tagging customer feedback.
If you want to test the audit trail on your own feedback rather than take the description on trust, book a demo.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.