



The 6 Steps to Build a Multi-Level Customer Feedback Taxonomy

September 30, 2026

Every jump in context window size revives the same idea: paste the whole quarter's feedback into a model, ask what customers are saying, and skip the platform. Enterpret research tested something close to that setup, repeatedly sending a full 5,000-record feedback dataset to a raw model. It cost roughly ten times more than querying a grounded system, about $143 for 15 raw runs against about $15. Fitting the data into the window turned out to be the easy part.
No, larger context windows will not make customer feedback platforms obsolete. They make one-off reads of feedback genuinely better, but the hard part of customer intelligence was never how much text a model can hold at once. Five reasons: reading more does not make the answer repeatable, rereading everything for every question is expensive, bigger inputs fail more often, a window holds text but not the customer behind it, and a window forgets everything when the session ends. A context window is a reading surface. It is not memory.
The build instinct here is right for a specific set of jobs. A long-context model can read a few hundred interview transcripts in one pass, give a first read on a channel nobody has analyzed, or draft a summary for a single launch retro without stitching chunks together. For those jobs, a bigger window removes real friction, and a platform adds little.
The trouble starts when the one-off read becomes a recurring number: the monthly theme report, the trend line in a QBR, the count that decides a roadmap slot. That is where the five reasons below apply.
A model that reads everything still invents the category structure from scratch on each run. In Enterpret research across eight frontier models, the most consistent one still changed roughly 60% of its themes between identical runs. A larger window lets the model see more records. It does not give it a reason to group them the same way twice, and a theme list that moves between runs cannot support a trend.
With a context-window approach, every question rereads the full dataset. Ask ten questions and the model reads the quarter ten times. A structured layer reads each record once, when it arrives, and answers later questions from what it already organized. The tenfold cost gap in the Enterpret scale study is that difference showing up on the bill, and it grows with both data volume and question volume.
In the same Enterpret scale study, 6 of 15 full-dataset runs at 5,000 records returned unusable output. Longer windows raise the ceiling on what fits, but they do not remove the failure mode at the top end, and real feedback volumes keep growing into whatever limit exists. A workflow that depends on one enormous call is only as reliable as that call.
The account a comment came from, the plan that account is on, its renewal date, and its revenue are not in the text of the feedback. A model can read every word and still not know that three complaints came from the same enterprise account up for renewal. In an exploratory Enterpret benchmark, analytical depth was where grounding mattered most: 0.967 for an agent grounded in a customer context graph versus 0.642 for both a deep research agent and agentic RAG. The difference was context attached to the feedback, not more feedback in the prompt.
Trends need the same categories applied month after month. A context window starts empty every session, so each month's analysis builds its own structure, and the results are not directly comparable. This is the core of the difference between zero-shot and learned feedback categorization: one regenerates categories each time, the other keeps them and updates them deliberately.
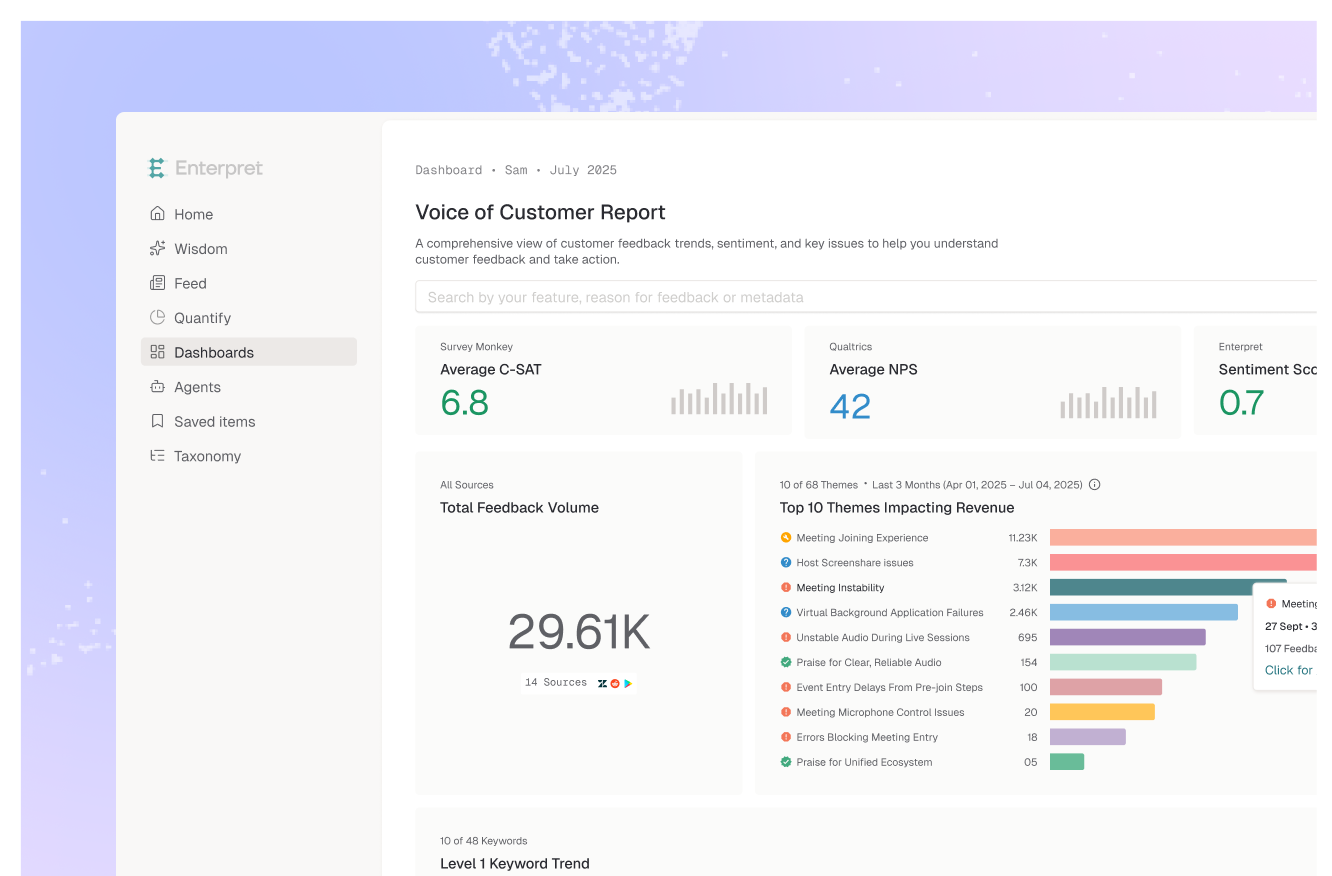
The question is not how much a model can read. It is what persists between reads. A feedback platform is the part that persists: the category structure, the customer context attached to each record, and the history that makes this month comparable to last month. Exploration without memory is the same trap described in why customer intelligence needs infrastructure.
Seen that way, larger windows make a platform more useful, not less. A model with a long window that reads structured, counted, account-linked themes spends its capacity reasoning over the customer picture instead of scanning raw text to rebuild it. The demo that works in a single session is real. The year of consistent, comparable answers is the part the window does not provide.
Some of it is. A fair test: swap the underlying model and see what survives. If the product is a prompt, a chat box, and a model call, nothing persists and it is a wrapper. If the product owns a category structure learned from your feedback, links each record to accounts and revenue, and keeps history comparable over time, the model is a replaceable component inside it. That distinction is the same one behind whether you can build customer intelligence with an LLM.
Enterpret is built around the parts a context window does not keep. Every record from 50+ sources is classified into an adaptive taxonomy learned from your own feedback and updated as your product changes, so categories persist across months. The customer context graph attaches each record to the account, segment, and revenue behind it. Models, including long-context ones, then query that structure through MCP, which is how a larger window becomes an advantage rather than a replacement.
No. Larger windows improve one-off reads of feedback, but they do not make results repeatable, keep categories stable across sessions, or attach account and revenue context that is not in the text. Those are what a feedback platform provides, and a long-context model works better on top of them.
For a one-off read of a few hundred records, often yes. For recurring analysis, pasting the full dataset each time is costly and the categories change between runs. Before doing it at all, review what to check before putting customer feedback into an LLM, and see using ChatGPT for customer feedback analysis for where direct use works best.
Some tools are. The test is what survives if the underlying model is swapped. A wrapper keeps nothing. A platform keeps a learned category structure, customer context for every record, and history that stays comparable over time, with the model as one replaceable part.
When the job is a single read that nobody will compare against a future read: a launch retro, a first pass on a new channel, or a summary of a batch of interviews. Once the output becomes a number tracked over time, it needs a fixed structure underneath.
Enterpret uses models inside a persistent structure rather than in place of one. Feedback is classified into an adaptive taxonomy and linked to accounts and revenue in the customer context graph, and models query that structure through MCP and other integrations, so answers draw on organized, comparable data.
If your team is weighing a long-context workflow against a platform, see how Enterpret's customer context graph works.
Lorem ipsum dolor sit amet, consectetur adipiscing elit. Suspendisse varius enim in eros elementum tristique. Duis cursus, mi quis viverra ornare, eros dolor interdum nulla, ut commodo diam libero vitae erat. Aenean faucibus nibh et justo cursus id rutrum lorem imperdiet. Nunc ut sem vitae risus tristique posuere.